Key Takeaways
- Act quickly when ransomware is suspected, using controlled containment rather than rushed decisions.
- Assign clear roles for investigation, communication, evidence preservation, and recovery.
- Isolate affected systems safely and protect compromised accounts, credentials, and backup infrastructure.
- Preserve relevant logs and evidence to support investigation and recovery.
- Restore services only after validating recovery points and addressing the original threat.
- Test backups, communication plans, and response procedures regularly to improve readiness.
A suspected ransomware event creates pressure to act immediately, but fast action only helps when it is organized. A practical ransomware incident response process at Cohesity provides teams with a shared approach to contain potential damage, preserve evidence, protect recovery options, and keep essential services operating. The goal of the first hour is not to solve every technical question. It is to make sound decisions under uncertainty. Teams should treat unusual encryption, ransom notes, suspicious administrator activity, unexpected data transfers, or widespread file changes as signals that justify prompt investigation and controlled containment.
Why the First Hour Matters
Ransomware incidents often involve more than file encryption. An attacker may have accessed accounts, moved between systems, copied data, or attempted to interfere with backups before a visible ransom demand appears. Waiting for certainty can allow an active intrusion to spread. Start the response when the risk is credible, then refine the scope as facts become available.
What to Prepare Before an Alert
Response quality depends heavily on preparation. Maintain a current inventory of critical applications, data stores, infrastructure dependencies, service owners, and recovery priorities. Keep incident contacts for IT, security, legal, communications, executive leadership, cyber insurance, and outside specialists in a location that remains available if normal systems are offline. Define who has authority to isolate a device, deactivate an account, restrict remote access, or declare a major incident. Store response playbooks, emergency contact lists, and recovery documentation outside the environment most likely to be affected. Also document recovery time objectives and recovery point objectives so restoration decisions support business needs rather than guesswork.
The First 15 Minutes
- Record the time, alert source, affected user, device, application, and visible symptoms.
- Notify the incident commander using a trusted out-of-band method, such as phone or text, if normal messaging may be compromised.
- Do not wipe, delete, or casually restart affected systems. Those actions can remove useful evidence.
- Isolate confirmed or strongly suspected devices from the network when it can be done safely.
- Review unusual activity involving privileged accounts, remote administration tools, VPN access, and identity systems.
- Open an incident log and assign one person to document actions, approvals, times, and findings.
How to Confirm and Contain a Suspected Incident
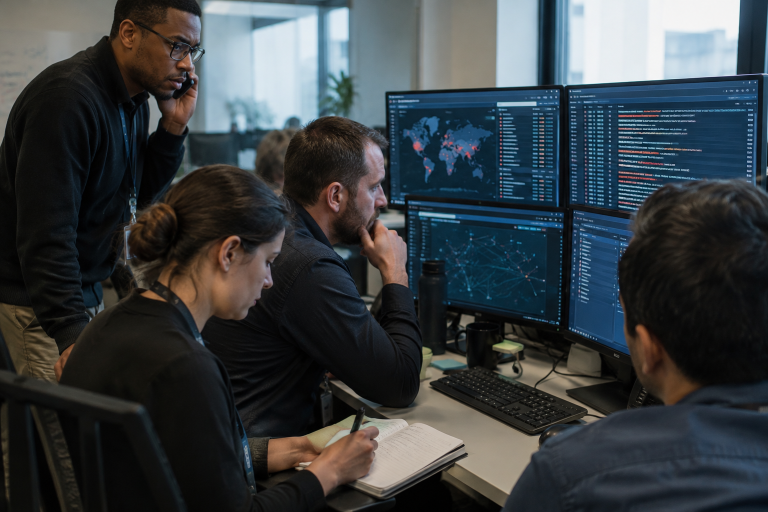
Review endpoint alerts, identity logs, firewall records, cloud activity, and recent file changes. Look for related signs across multiple systems, including failed authentication bursts, new administrator accounts, unusual login locations, unexpected remote tools, or abnormal access to shared data. A single device problem may be limited, but evidence of lateral movement or credential misuse requires broader action. Containment should prevent further harm without creating unnecessary confusion. Federal guidance advises organizations to isolate affected systems and preserve volatile evidence during a ransomware response. Disable suspected compromised accounts, rotate exposed credentials, review vendor and remote-access connections, and protect backup consoles and recovery accounts. Avoid a broad shutdown unless it is necessary to stop active spread, as a rushed shutdown can disrupt critical services and complicate the investigation.
Protect Evidence Before It Disappears
Evidence supports technical investigation, insurance processes, legal review, notifications, and future prevention. Preserve relevant logs, alerts, ransom notes, file extensions, timestamps, affected host details, and suspicious files. Capture system and memory evidence through qualified personnel when possible, especially when an attacker may still have access. Document every containment decision, including who approved it and why. Keep collected information separate from potentially compromised systems. If the event exceeds internal capabilities, engage forensic and incident response specialists early enough to help preserve evidence and identify the initial access path.
Roles and Decision Rights
Clear ownership prevents a technical incident from becoming a coordination failure. Assign named primary and backup owners for these responsibilities:
- Incident commander: Sets priorities, coordinates teams, and approves major decisions.
- Technical lead: Directs investigation, isolation, eradication, and validation work.
- Identity lead: Protects accounts, credentials, access pathways, and privileged roles.
- Legal advisor: Reviews contractual, privacy, regulatory, and notification considerations.
- Communications lead: Prepares accurate updates for employees, customers, and partners.
- Recovery lead: Coordinates clean restoration and verifies that services are safe to return.
Keep Critical Operations Running
Incident response is also a business continuity exercise. Rank essential functions by urgency and identify workable manual alternatives for customer support, payroll, shipping, healthcare delivery, production, or other core operations. Decide in advance which systems can remain offline and which services require priority restoration. Department leaders should help validate those choices because technical importance and business importance are not always the same.
Plan a Safe Recovery
Recovery should occur in stages. First, confirm the immediate threat is contained and assess whether identity platforms, backup systems, administrative tools, or recovery accounts were affected. Then select verified recovery points, restore critical services on a clean environment where appropriate, and monitor closely for signs of persistence or reinfection. Organizations benefit from treating incident response as part of cybersecurity risk management, rather than as an isolated technical activity. Record what was restored, what remains at risk, and what controls must change before the next recovery phase begins.
Communication, Testing, and Common Mistakes
Use one approved channel for internal updates, separate confirmed facts from open questions, and set a predictable update schedule. Coordinate external statements with legal and executive teams. Do not share sensitive technical details widely, particularly when attacker access cannot be ruled out. Test the plan through regular tabletop exercises and recovery drills. Include scenarios involving stolen credentials, data extortion without encryption, compromised backups, and unavailable email. Common mistakes include waiting for a ransom note, coordinating through compromised tools, restoring before investigating initial access, overlooking privileged accounts, and assuming backups will work without testing them.
Ransomware Readiness Checklist
- Named incident commander and backup
- Current asset, data, and dependency inventory
- Trusted out-of-band communication method
- Authority to isolate systems and deactivate accounts
- Protected, tested recovery points
- Documented containment and evidence-handling steps
- Legal, insurance, and specialist response contacts
- Recovery priorities for essential services
- Recent tabletop and restoration test results
- Post-incident review process
Conclusion
The strongest ransomware response plan is not necessarily the longest one. It is the plan that helps people recognize danger early, act within clear authority, preserve what matters, communicate calmly, and restore essential operations without reintroducing the threat. To achieve this, organizations need clearly defined responsibilities, practical response procedures, and reliable communication channels that remain useful under pressure. Employees should understand how to report suspicious activity, while IT and security teams should know who can authorize containment measures, isolate affected systems, and coordinate outside assistance. Maintaining current backups, testing recovery procedures, and keeping an accurate inventory of critical systems can also help reduce disruption during an incident. Just as important, teams should preserve relevant logs and evidence, document major decisions, and communicate verified information to leadership and other stakeholders without spreading speculation. Recovery should follow a controlled process that includes verifying system integrity, addressing the original weakness, and monitoring for signs of renewed activity before affected services resume normal use. Regular exercises can reveal unclear responsibilities and missing steps before a real incident exposes them. By combining preparation, disciplined execution, and lessons learned from each exercise or event, organizations can build a ransomware response plan that enables faster decision-making, more reliable recovery, and greater resilience over time.

